VLABench#
← 教程资料库 · 仿真与基准
本节介绍 LeRobot 的通用功能。请按目标机器人、数据集和运行环境配置示例;用于 AlohaMini 2 / 2 Pro 前,需要确认硬件与接口兼容性。
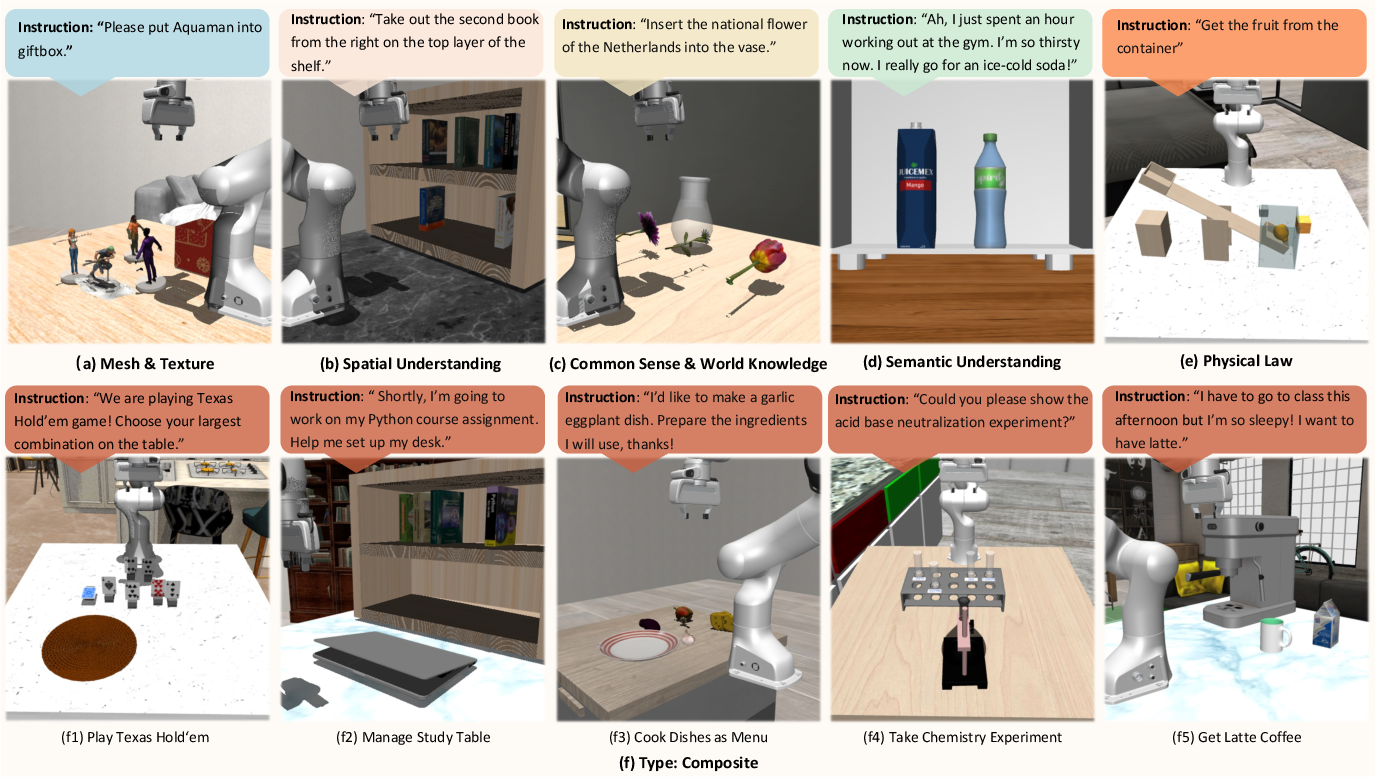
VLABench is a large-scale benchmark for language-conditioned robotic manipulation with long-horizon reasoning. The upstream suite covers 100 task categories across 2,000+ objects and evaluates six dimensions of robot intelligence: mesh & texture understanding, spatial reasoning, world-knowledge transfer, semantic instruction comprehension, physical-law understanding, and long-horizon planning. Built on MuJoCo / dm_control with a Franka Panda 7-DOF arm. LeRobot exposes 43 of these tasks through --env.task (21 primitives + 22 composites, see Available tasks below).
GitHub: OpenMOSS/VLABench
Project website: vlabench.github.io
Pretrained policy:
lerobot/smolvla_vlabench
Available tasks#
VLABench ships two task suites covering 43 task categories in LeRobot's --env.task surface:
Suite |
CLI name |
Tasks |
Description |
|---|---|---|---|
Primitive |
|
21 |
Single / few-skill combinations (select, insert, physics QA) |
Composite |
|
22 |
Multi-step reasoning and long-horizon planning (cook, rearrange) |
Primitive tasks: select_fruit, select_toy, select_chemistry_tube, add_condiment, select_book, select_painting, select_drink, insert_flower, select_billiards, select_ingredient, select_mahjong, select_poker, and physical-reasoning tasks (density_qa, friction_qa, magnetism_qa, reflection_qa, simple_cuestick_usage, simple_seesaw_usage, sound_speed_qa, thermal_expansion_qa, weight_qa).
Composite tasks: cluster_billiards, cluster_book, cluster_drink, cluster_toy, cook_dishes, cool_drink, find_unseen_object, get_coffee, hammer_nail, heat_food, make_juice, play_mahjong, play_math_game, play_poker, play_snooker, rearrange_book, rearrange_chemistry_tube, set_dining_table, set_study_table, store_food, take_chemistry_experiment, use_seesaw_complex.
--env.task accepts three forms:
a single task name (
select_fruit)a comma-separated list (
select_fruit,heat_food)a suite shortcut (
primitive,composite, orprimitive,composite)
Installation#
VLABench is not on PyPI — its only distribution is the OpenMOSS/VLABench GitHub repo — so LeRobot does not expose a vlabench extra. Install it manually as an editable clone, alongside the MuJoCo / dm_control pins VLABench needs, then fetch the mesh assets:
# After following the standard LeRobot installation instructions.

git clone https://github.com/OpenMOSS/VLABench.git ~/VLABench
git clone https://github.com/motion-planning/rrt-algorithms.git ~/rrt-algorithms
pip install -e ~/VLABench -e ~/rrt-algorithms
pip install "mujoco==3.2.2" "dm-control==1.0.22" \
            open3d colorlog scikit-learn openai gdown

python ~/VLABench/scripts/download_assets.py
提示
VLABench requires Linux (sys_platform == 'linux') and Python 3.10+. Set the MuJoCo rendering backend before running:
export MUJOCO_GL=egl # for headless servers (HPC, cloud)
Evaluation#
All eval snippets below mirror the command CI runs (see .github/workflows/benchmark_tests.yml). The --rename_map argument maps VLABench's image / second_image / wrist_image camera keys onto the three-camera (camera1 / camera2 / camera3) input layout the released smolvla_vlabench policy was trained on.
Single-task evaluation (recommended for quick iteration)#
lerobot-eval \
  --policy.path=lerobot/smolvla_vlabench \
  --env.type=vlabench \
  --env.task=select_fruit \
  --eval.batch_size=1 \
  --eval.n_episodes=10 \
  --eval.use_async_envs=false \
  --policy.device=cuda \
  '--rename_map={"observation.images.image": "observation.images.camera1", "observation.images.second_image": "observation.images.camera2", "observation.images.wrist_image": "observation.images.camera3"}'
Multi-task evaluation#
Pass a comma-separated list of tasks:
lerobot-eval \
  --policy.path=lerobot/smolvla_vlabench \
  --env.type=vlabench \
  --env.task=select_fruit,select_toy,add_condiment,heat_food \
  --eval.batch_size=1 \
  --eval.n_episodes=10 \
  --eval.use_async_envs=false \
  --policy.device=cuda \
  '--rename_map={"observation.images.image": "observation.images.camera1", "observation.images.second_image": "observation.images.camera2", "observation.images.wrist_image": "observation.images.camera3"}'
Suite-wide evaluation#
Run an entire suite (all 21 primitives or all 22 composites):
lerobot-eval \
  --policy.path=lerobot/smolvla_vlabench \
  --env.type=vlabench \
  --env.task=primitive \
  --eval.batch_size=1 \
  --eval.n_episodes=10 \
  --eval.use_async_envs=false \
  --policy.device=cuda \
  --env.max_parallel_tasks=1 \
  '--rename_map={"observation.images.image": "observation.images.camera1", "observation.images.second_image": "observation.images.camera2", "observation.images.wrist_image": "observation.images.camera3"}'
Or both suites:
lerobot-eval \
  --policy.path=lerobot/smolvla_vlabench \
  --env.type=vlabench \
  --env.task=primitive,composite \
  --eval.batch_size=1 \
  --eval.n_episodes=10 \
  --eval.use_async_envs=false \
  --policy.device=cuda \
  --env.max_parallel_tasks=1 \
  '--rename_map={"observation.images.image": "observation.images.camera1", "observation.images.second_image": "observation.images.camera2", "observation.images.wrist_image": "observation.images.camera3"}'
Recommended evaluation episodes#
10 episodes per task for reproducible benchmarking (210 total for the full primitive suite, 220 for composite). Matches the protocol in the VLABench paper.
Policy inputs and outputs#
Observations:
observation.state— 7-dim end-effector state (position xyz + Euler xyz + gripper)observation.images.image— front camera, 480×480 HWC uint8observation.images.second_image— second camera, 480×480 HWC uint8observation.images.wrist_image— wrist camera, 480×480 HWC uint8
Actions:
Continuous control in
Box(-1, 1, shape=(7,))— 3D position + 3D Euler orientation + 1D gripper.
Training#
Datasets#
Pre-collected VLABench datasets in LeRobot format on the Hub:
VLABench/vlabench_primitive_ft_lerobot_video— 5,000 episodes, 128 tasks, 480×480 images.VLABench/vlabench_composite_ft_lerobot_video— 5,977 episodes, 167 tasks, 224×224 images.
Example training command#
Fine-tune a SmolVLA base on the primitive suite:
lerobot-train \
  --policy.type=smolvla \
  --policy.repo_id=${HF_USER}/smolvla_vlabench_primitive \
  --policy.load_vlm_weights=true \
  --policy.push_to_hub=true \
  --dataset.repo_id=VLABench/vlabench_primitive_ft_lerobot_video \
  --env.type=vlabench \
  --env.task=select_fruit \
  --output_dir=./outputs/smolvla_vlabench_primitive \
  --steps=100000 \
  --batch_size=4 \
  --env_eval_freq=5000 \
  --eval.batch_size=1 \
  --eval.n_episodes=1 \
  --save_freq=10000
Reproducing published results#
The released checkpoint lerobot/smolvla_vlabench was trained on the primitive-suite dataset above and is evaluated with the Single-task / Suite-wide commands. CI runs a 10-primitive-task smoke eval (one episode each) on every PR touching the benchmark.